Overview
Gemini has amazed the world with its capability to understand hour-long videos. However, we still lack an open-source alternative with similar capabilities. Our latest research presents an innovative solution towards long video LMM, shifting the focus from reducing visual tokens per frame to leveraging the long context capabilities of language models.
Here, we present our state-of-the-art video model, Long Video Assistant (LongVA), and our novel benchmark, Visual Needle-In-A-Haystack (V-NIAH).
Key Innovations
🔄 Long Context Transfer
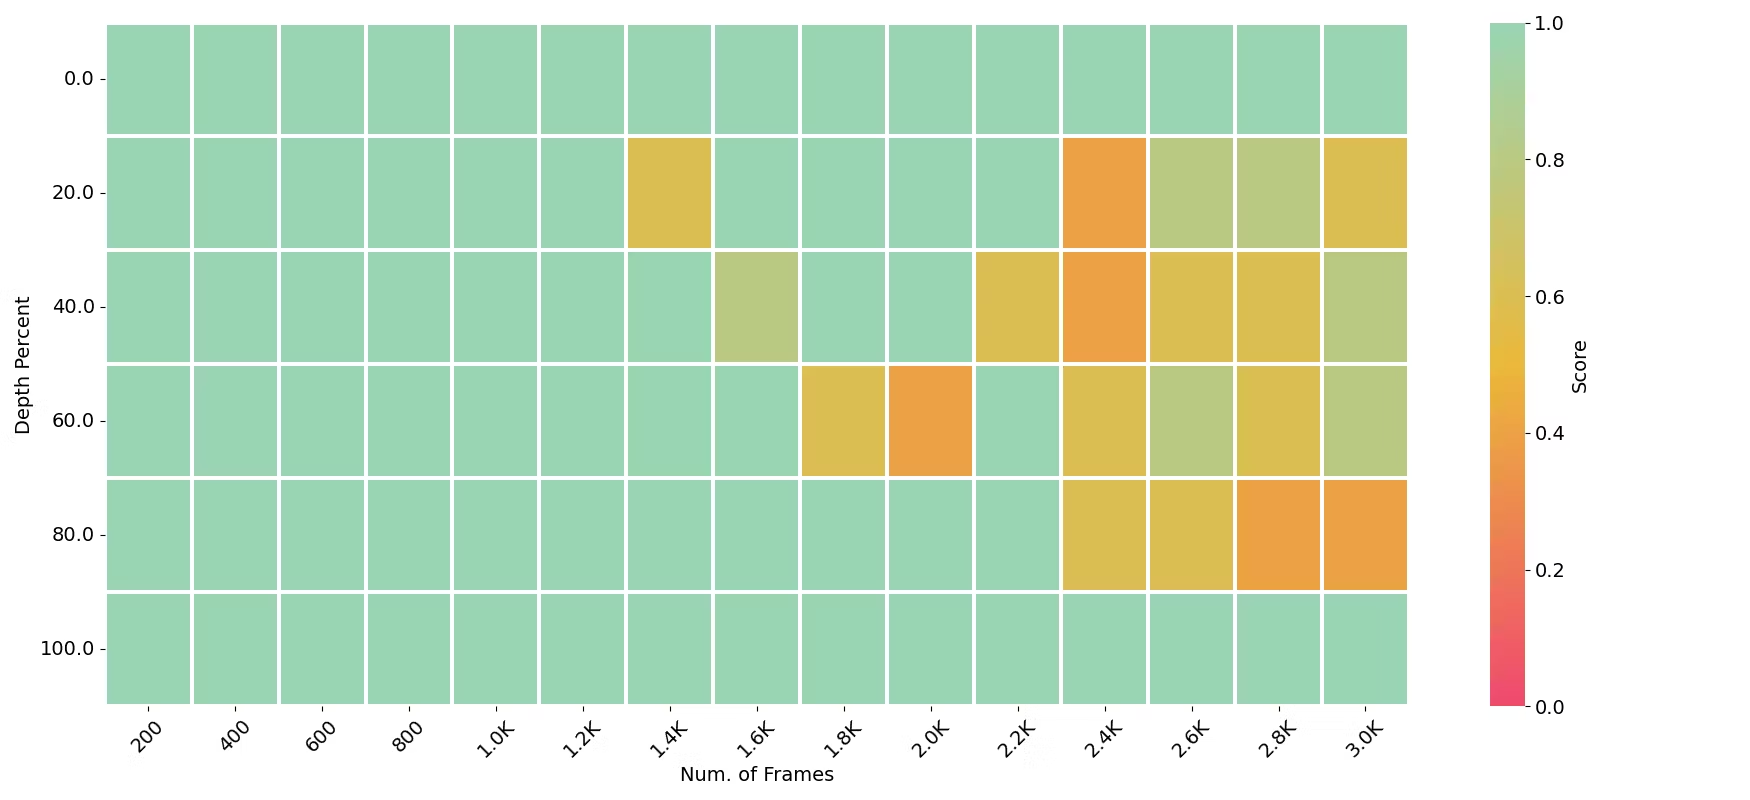
We discovered and verified that the long context capability of language models can be directly transferred to the video domain in modality-aligned multi-modal models. On V-NIAH, LongVA is the only open-source model capable of accurately retrieving visual information from inputs with:
- 2000+ frames
- 200K+ visual tokens
🎯 UniRes: Unified Visual Encoding
We proposed UniRes, a unified visual encoding scheme that encodes both images and videos. In UniRes, a video is encoded the same as multiple image crops in a sequence.
Key Benefits:
- Leverages the Long Context Transfer property
- Enables superior zero-shot performance in video tasks
- No video-specific training data required
Performance Highlights
🏆 State-of-the-Art Results
LongVA achieves state-of-the-art performance on the comprehensive Video-MME benchmarks among 7B models.
Key Performance Features:
- Performance increases with denser sampling of video frames
- Superior zero-shot capabilities on video understanding tasks
- Comprehensive ablation studies validating improvement sources
📊 V-NIAH Benchmark
Our novel Visual Needle-In-A-Haystack (V-NIAH) benchmark provides:
- Rigorous evaluation of long-context visual understanding
- Testing retrieval accuracy across extended video sequences
- Open-source evaluation framework for the community
Technical Architecture
Multi-Modal Alignment
LongVA demonstrates that language models' inherent long-context capabilities can be effectively transferred to visual domains through proper modality alignment.
Scalable Design
The architecture scales efficiently with:
- Increased frame sampling rates
- Extended sequence lengths
- Larger visual token counts
Research Impact
Open-Source Alternative
LongVA provides the first viable open-source alternative to proprietary long-video understanding systems, enabling:
- Academic research advancement
- Commercial application development
- Community-driven improvements
Methodology Innovation
The long context transfer approach opens new research directions in:
- Cross-modal capability transfer
- Efficient video processing
- Unified multi-modal architectures
Future Directions
LongVA establishes a foundation for:
- Extended Context Models - Pushing beyond current frame limits
- Multi-Modal Transfer Learning - Applying insights to other modalities
- Efficient Video Processing - Optimizing computational requirements
- Benchmark Development - Creating more comprehensive evaluation metrics
Open research
LongVA Resources
Complete resources for LongVA including source code, evaluation benchmark, and pre-trained models
Acknowledgements
This work presents an innovative approach to long video understanding by leveraging language model capabilities, developed by the Evolving LMMs Lab and collaborating institutions.
BibTeX
@article{zhang2024longva,
  title={LongVA: Long Context Transfer from Language to Vision},
  author={Zhang, Peiyuan and Zhang, Kaichen and Li, Bo and Zeng, Guangtao and Yang, Jingkang and Zhang, Yuanhan and Wang, Ziyue and Tan, Haoran and Li, Chunyuan and Liu, Ziwei},
  journal={arXiv preprint arXiv:2406.16852},
  year={2024}
}