LLaVA-OneVision-2: Towards Next-Generation Perceptual Intelligence
The next generation of fully-open multimodal training — pushing the boundary of recipe transparency, native-resolution understanding, and end-to-end reproducibility.
Codec evidence keeps motion dense where uniform frames go sparse.Codec 证据在动作密集处保留更多视觉信息,而均匀抽帧容易变稀疏。
The same jump-rope clip is rendered side-by-side on a shared source-video timeline: uniform sampling sees only 128 evenly spaced frames, while codec-selected patches follow the retained temporal evidence.同一段跳绳视频在共享原视频时间轴上并排渲染:均匀采样只看到 128 个等距帧,而 codec-selected patches 会跟随被保留下来的时序证据。
Same timeline, different temporal evidence同一时间轴,不同的视频证据密度
Highlights核心要点
LLaVA-OneVision-2 is a fully-open recipe for training competitive 8B-class vision-language models — every stage, every dataset, every weight is reproducible. Below: what makes it different at a glance.LLaVA-OneVision-2 是一套完全开放的 8B 级视觉语言模型训练配方——每个阶段、每个数据集、每份权重都可复现。下方为其核心特性概览。
Long Video Understanding长视频理解
Codec-based InputCodec 类型输入
Fully Open Pipeline全流程开源
Roadmap路线图
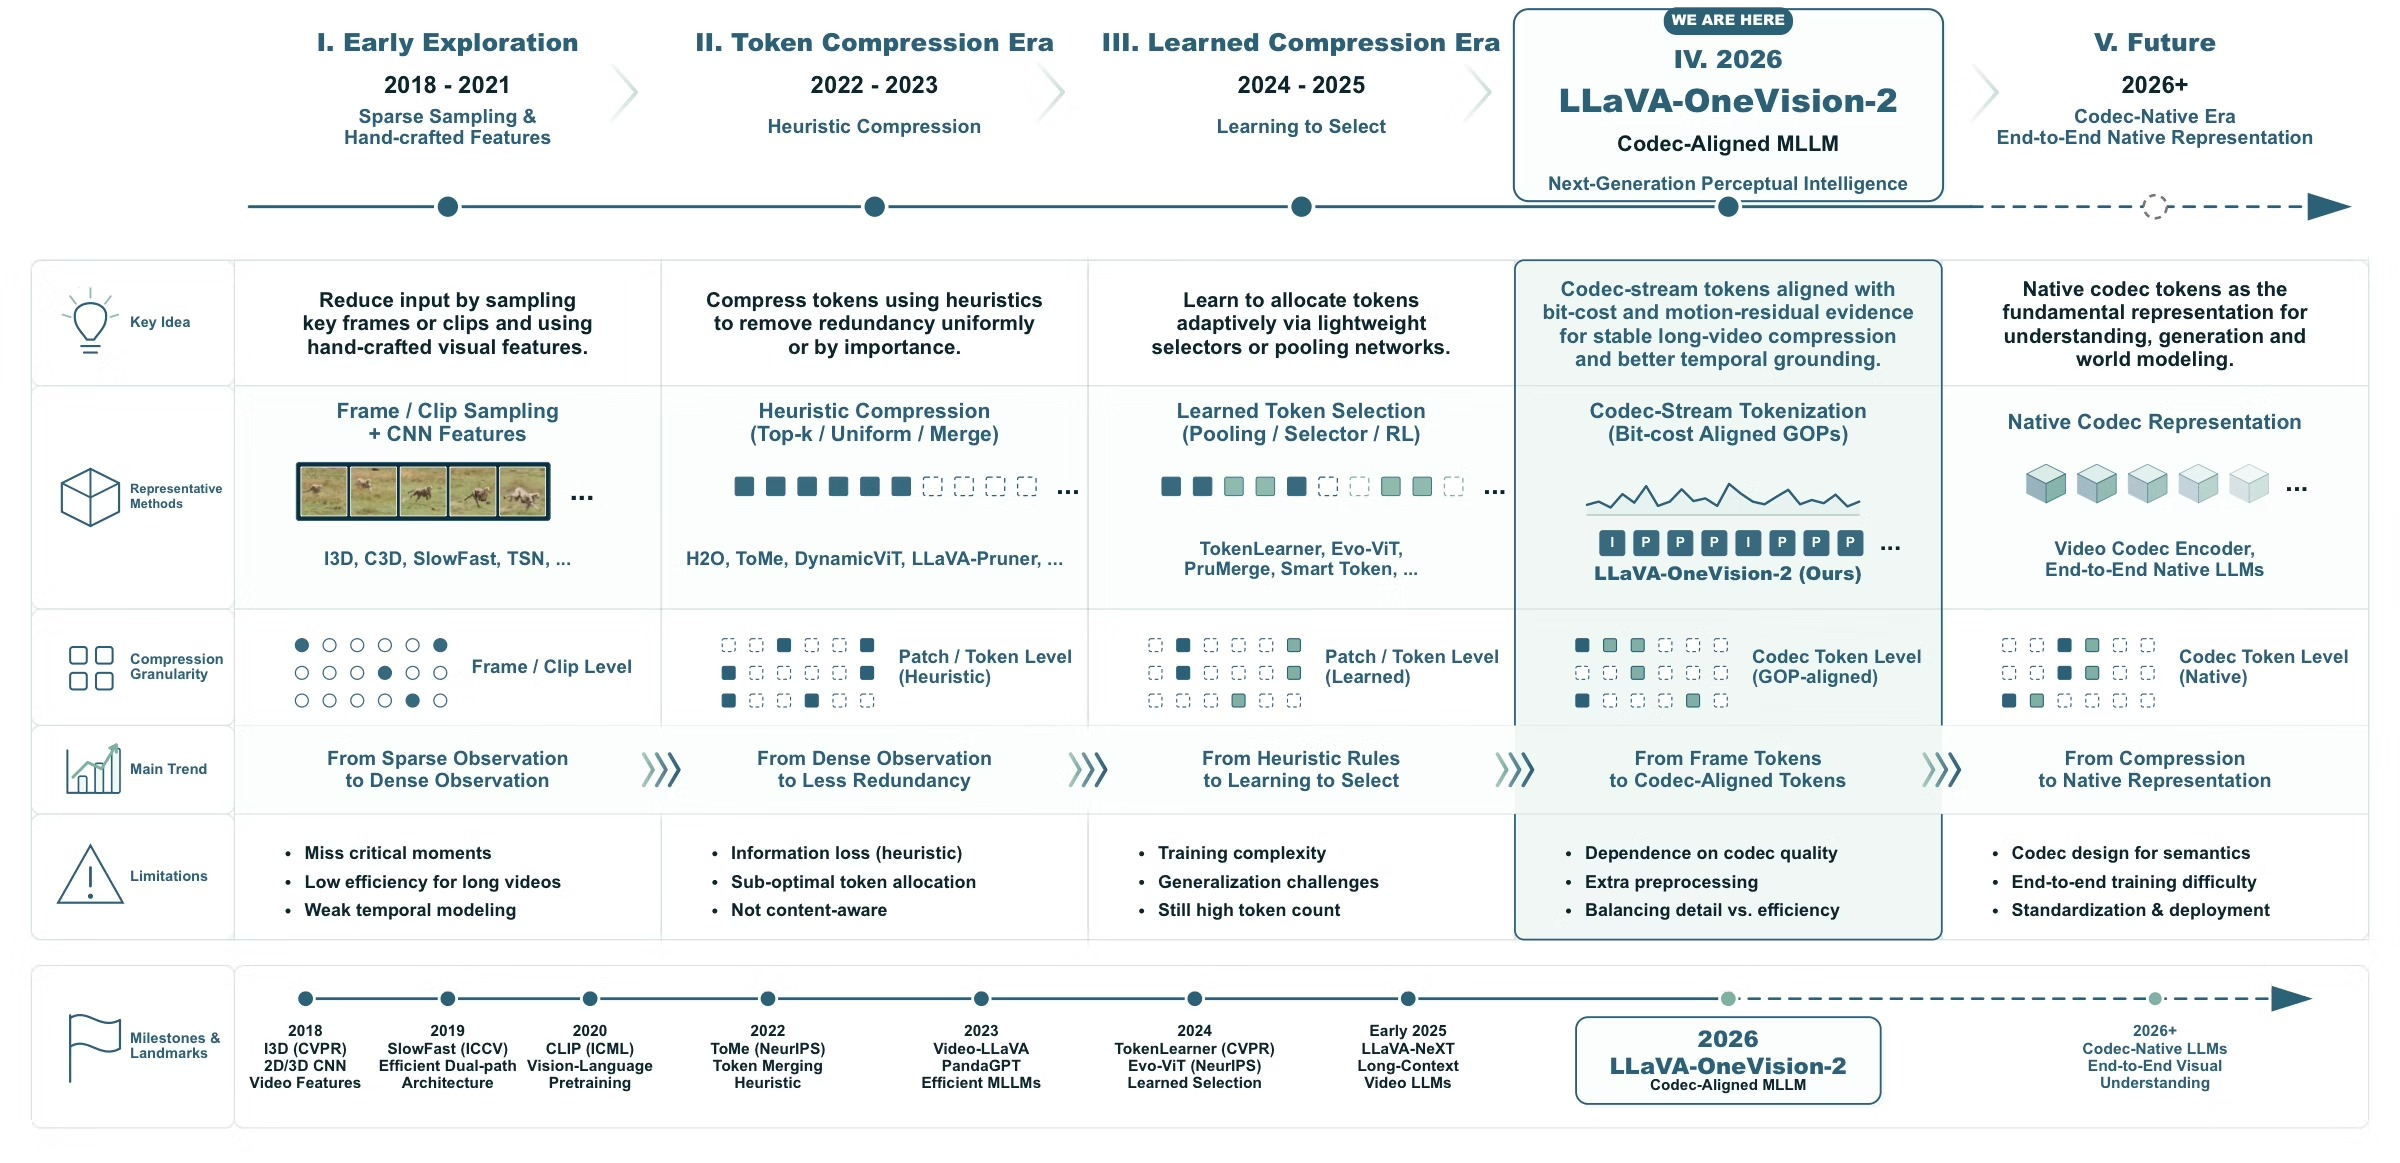
The OV2 roadmap traces the evolution from early frame and clip sampling to heuristic token compression, learned token selection, and the 2026 codec-aligned paradigm.
How It Works方法图解
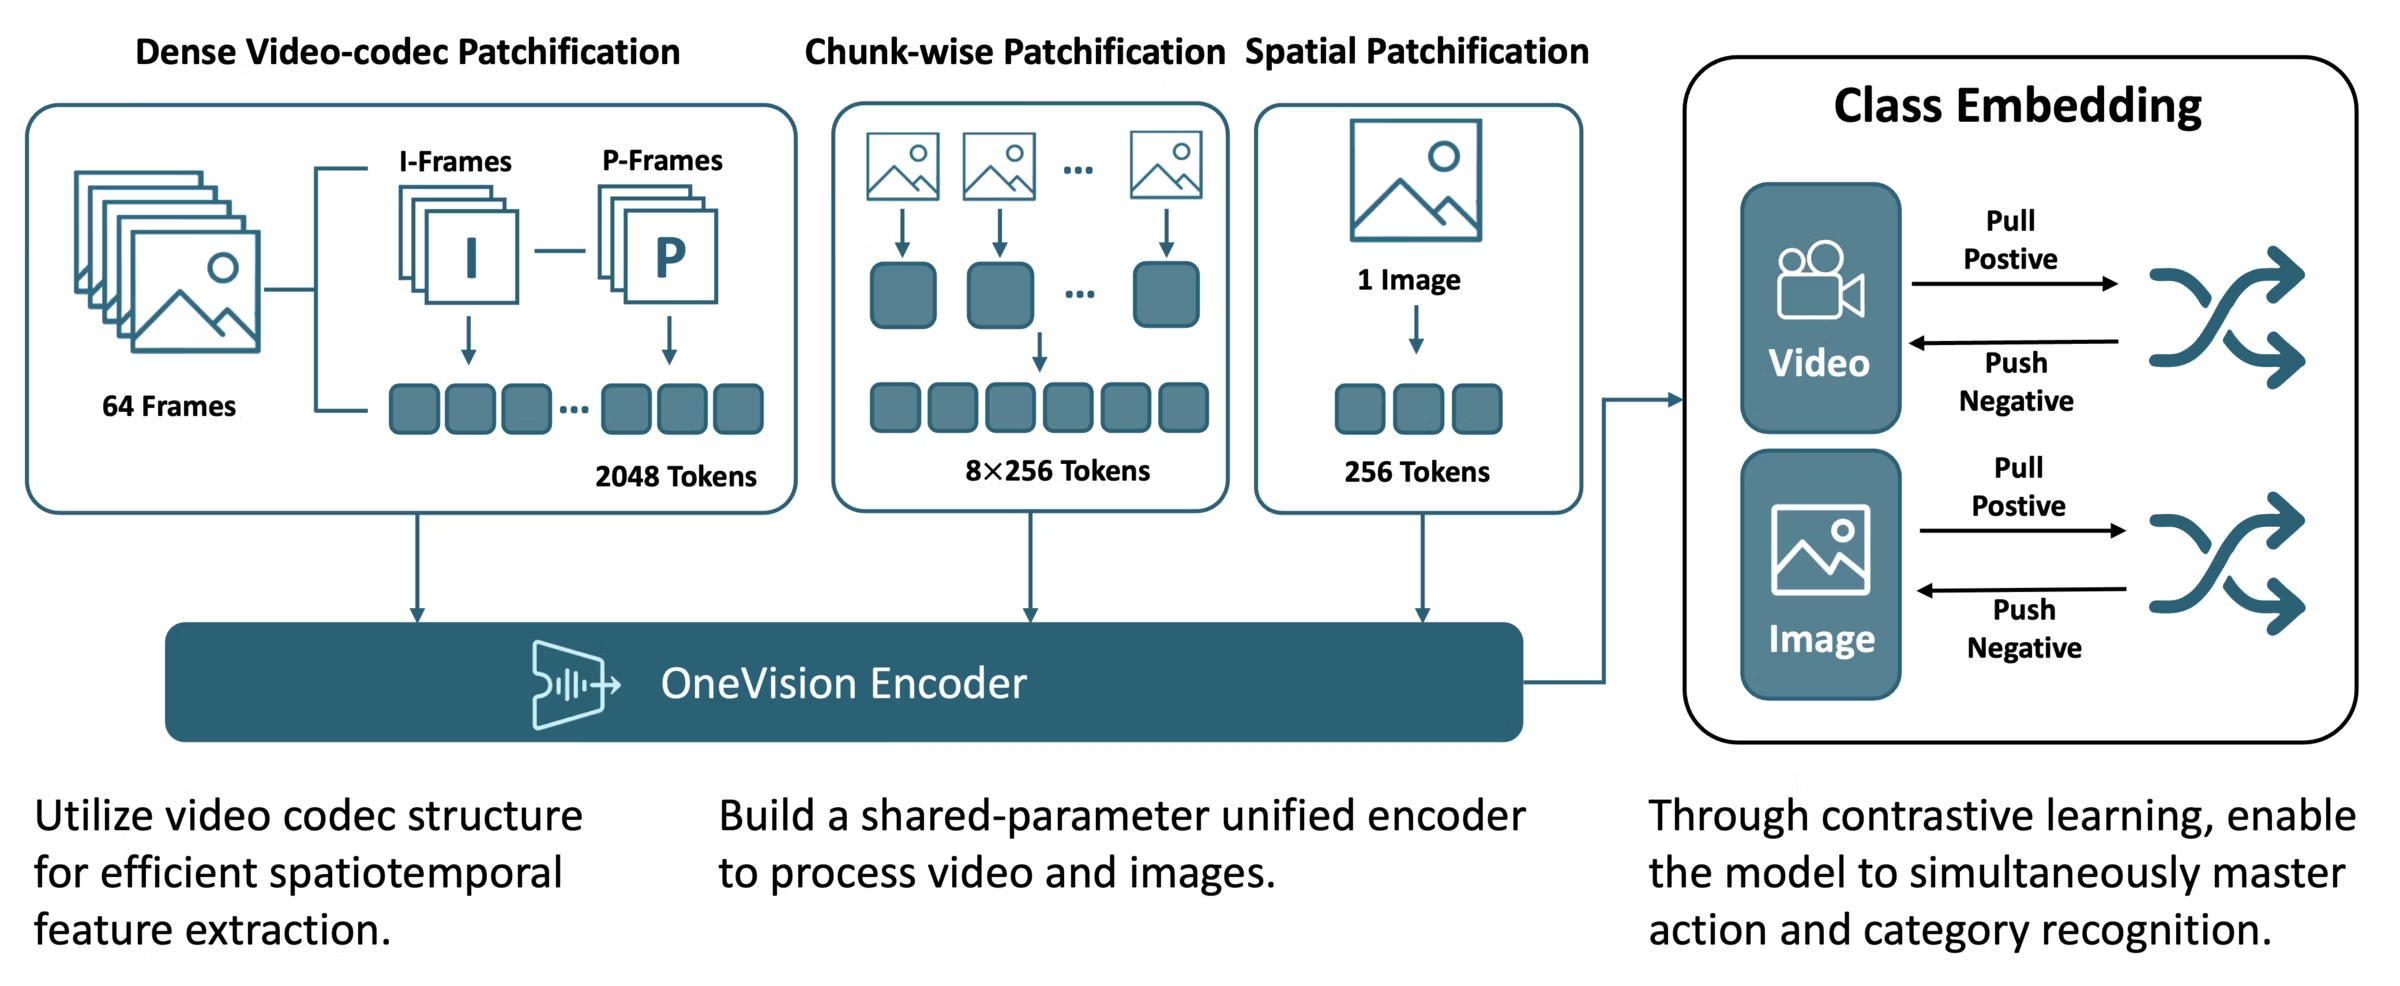
Two design choices behind LLaVA-OneVision-2's long-video and unified-modality capability, illustrated.
LLaVA-OneVision-2 长视频与多模态统一能力背后的两个核心设计,图示如下。
(t, h, w) positions.图 4. 单一编码器统一处理三种模态输入。图像、均匀帧视频与 codec 对齐视频均通过同一 OneVision-Encoder,并共享 (t, h, w) 位置编码。Benchmarks基准测试
| Benchmark | LLaVA-OneVision-2 8B | Qwen3-VL 8B | Keye-VL-1.5 8B | InternVL-3.5 8B | PLM 8B | LLaVA-OV-1.5 8B |
|---|---|---|---|---|---|---|
| 71.9 | 71.4 | 73.0 | 65.9 | 60.5 | 61.1 | |
Resolution Distribution分辨率分布 Duration Distribution (min)时长分布 (分钟) | ||||||
| 76.3 | 75.6 | 76.2 | 68.6 | 65.6 | 65.5 | |
| 19.9 | 18.2 | 14.1 | 14.6 | 8.7 | 9.1 | |
| 55.5 | 58.0 | 42.8 | 46.7 | 44.5 | 40.1 | |
Resolution Distribution分辨率分布 Duration Distribution (min)时长分布 (分钟) | ||||||
| 61.5 | 59.2 | 54.9 | 50.1 | 47.2 | 44.8 | |
Resolution Distribution分辨率分布 Duration Distribution (min)时长分布 (分钟) | ||||||
| 66.2 | 69.0 | 56.9 | 72.1 | 77.1 | 51.2 | |
| 82.5 | 83.4 | 75.8 | 82.0 | 84.1 | 73.7 | |
Resolution Distribution分辨率分布 Duration Distribution (s)时长分布 (秒) | ||||||
| 74.5 | 74.3 | 75.5 | 70.4 | 72.7 | 57.5 | |
Resolution Distribution分辨率分布 Duration Distribution (s)时长分布 (秒) | ||||||
| 76.6 | 78.1 | 75.0 | 71.0 | 66.4 | 62.1 | |
Resolution Distribution分辨率分布 Duration Distribution (min)时长分布 (分钟) | ||||||
| 66.9 | 68.0 | 66.0 | 62.4 | 59.6 | 56.2 | |
Resolution Distribution分辨率分布 Duration Distribution (min)时长分布 (分钟) | ||||||
| 56.2 | 58.7 | 68.3 | 60.2 | 43.3 | 50.1 | |
Resolution Distribution分辨率分布 Duration Distribution (s)时长分布 (秒) | ||||||
| 39.5 | 40.6 | 35.3 | 36.1 | 26.2 | 30.7 | |
Resolution Distribution分辨率分布 Duration Distribution (min)时长分布 (分钟) | ||||||
| 53.5 | 48.3 | 45.4 | 27.8 | 34.5 | 15.6 | |
Resolution Distribution分辨率分布 Duration Distribution (s)时长分布 (秒) | ||||||
| 53.8 | 46.8 | 41.3 | 31.3 | 7.6 | 17.7 | |
Resolution Distribution分辨率分布 Duration Distribution (s)时长分布 (秒) | ||||||
| 66.4 | 59.4 | 55.5 | 31.3 | 4.2 | 21.0 | |
Resolution Distribution分辨率分布 Duration Distribution (s)时长分布 (秒) | ||||||
| 74.9 | 30.1 | 39.6 | 11.0 | 13.1 | 2.1 | |
Resolution Distribution分辨率分布 Duration Distribution (s)时长分布 (秒) | ||||||
| 70.9 | 59.1 | 36.4 | 56.0 | 27.9 | 30.2 | |
Resolution Distribution分辨率分布 Duration Distribution (min)时长分布 (分钟) | ||||||
| 57.6 | 48.9 | 32.4 | 47.9 | 30.7 | 33.5 | |
Resolution Distribution分辨率分布 Duration Distribution (min)时长分布 (分钟) | ||||||
| Average | 62.5 | 58.2 | 53.6 | 50.3 | 43.0 | 40.1 |
| Benchmark | LLaVA-OneVision-2 8B | Qwen3-VL 8B | Keye-VL-1.5 8B | InternVL-3.5 8B | PLM 8B | LLaVA-OV-1.5 8B |
|---|---|---|---|---|---|---|
| 77.3 | 77.7 | 75.2 | 75.0 | 77.0 | 74.8 | |
| 69.1 | 68.7 | 59.2 | 65.7 | 45.4 | 67.1 | |
| 43.3 | 42.3 | 38.3 | 41.8 | 44.3 | 41.5 | |
Resolution Distribution分辨率分布 | ||||||
| 82.6 | 81.0 | 78.2 | 77.9 | 80.6 | 76.5 | |
Resolution Distribution分辨率分布 | ||||||
| 92.8 | 92.3 | 82.0 | 86.3 | 82.4 | 82.9 | |
Resolution Distribution分辨率分布 | ||||||
| 61.9 | 26.9 | 20.2 | 20.2 | 15.7 | 15.9 | |
Resolution Distribution分辨率分布 | ||||||
| 78.1 | 77.5 | 66.3 | 73.2 | 73.5 | 64.2 | |
Resolution Distribution分辨率分布 | ||||||
| 69.3 | 69.3 | 62.7 | 54.7 | 36.7 | 61.3 | |
Resolution Distribution分辨率分布 | ||||||
| 29.6 | 31.0 | 26.7 | 28.1 | 31.4 | 28.3 | |
| 63.5 | 65.1 | 52.2 | 55.7 | 56.0 | 48.3 | |
Resolution Distribution分辨率分布 | ||||||
| 31.0 | 8.0 | 3.0 | 4.0 | 1.0 | 1.0 | |
Resolution Distribution分辨率分布 | ||||||
| Average | 63.5 | 58.2 | 51.3 | 53.0 | 49.5 | 51.1 |
| Benchmark | LLaVA-OneVision-2 8B | Qwen3-VL 8B | Keye-VL-1.5 8B | InternVL-3.5 8B | PLM 8B | LLaVA-OV-1.5 8B |
|---|---|---|---|---|---|---|
| 64.8 | 62.9 | 73.6 | 66.6 | 57.9 | 67.9 | |
Resolution Distribution分辨率分布 | ||||||
| 85.7 | 84.9 | 88.5 | 87.9 | 80.2 | 85.6 | |
Resolution Distribution分辨率分布 | ||||||
| 95.2 | 95.7 | 94.9 | 92.3 | 94.6 | 97.8 | |
Resolution Distribution分辨率分布 | ||||||
| 85.9 | 85.1 | 84.7 | 86.7 | 85.5 | 86.5 | |
Resolution Distribution分辨率分布 | ||||||
| 74.4 | 83.4 | 76.9 | 79.1 | 80.0 | 79.1 | |
Resolution Distribution分辨率分布 | ||||||
| 78.2 | 84.7 | 84.8 | 84.0 | 83.2 | 82.6 | |
Resolution Distribution分辨率分布 | ||||||
| 84.3 | 83.6 | 86.0 | 84.0 | 92.7 | 84.0 | |
Resolution Distribution分辨率分布 | ||||||
| 85.9 | 85.3 | 78.0 | 81.7 | 71.2 | 77.5 | |
Resolution Distribution分辨率分布 | ||||||
| 89.0 | 89.8 | 83.1 | 75.6 | 91.8 | 87.8 | |
Resolution Distribution分辨率分布 | ||||||
| 64.0 | 62.4 | 55.6 | 61.8 | 68.0 | 63.1 | |
Resolution Distribution分辨率分布 | ||||||
| 69.7 | 69.4 | 69.8 | 63.1 | 72.7 | 68.1 | |
Resolution Distribution分辨率分布 | ||||||
| Average | 79.7 | 80.7 | 79.6 | 78.4 | 79.8 | 80.0 |
| Benchmark | LLaVA-OneVision-2 8B | Qwen3-VL 8B | Keye-VL-1.5 8B | InternVL-3.5 8B | PLM 8B | LLaVA-OV-1.5 8B |
|---|---|---|---|---|---|---|
| 52.7 | 39.7 | 14.6 | 12.8 | 7.8 | 11.9 | |
| 58.7 | 41.3 | 5.8 | 4.7 | 2.0 | 4.1 | |
| 37.1 | 29.9 | 10.1 | 7.2 | 5.0 | 7.3 | |
| 45.7 | 28.4 | 7.2 | 7.5 | 7.6 | 6.1 | |
| 60.8 | 40.7 | 22.1 | 22.2 | 6.8 | 16.8 | |
| 58.2 | 37.8 | 10.7 | 10.2 | 8.5 | 13.0 | |
| 27.4 | 24.7 | 9.9 | 7.9 | 0.1 | 6.2 | |
| 29.2 | 21.9 | 9.6 | 9.2 | 10.2 | 9.7 | |
| Average | 46.2 | 33.1 | 11.3 | 10.2 | 6.0 | 9.4 |
Codec vs Frame Sampling编解码采样 vs 均匀帧采样
At equal token budgets, codec-stream input consistently wins under tight frame budgets — exactly the regime where uniform sampling fails the model.
Video Caption Dataset视频描述数据集
A length-stratified video caption corpus spanning 30 seconds to 15 minutes, totaling roughly 8M captioned clips, 95.1B image tokens, and 9.9B caption tokens.
| Bucket | Samples | Storage | Image Tokens | Caption Tokens |
|---|---|---|---|---|
| 30s caption | 4.2M | 29 TB | 24.7B | 3.0B |
| 30–60s video caption | 2.7M | 32 TB | 31.8B | 2.3B |
| 60–180s video caption | 700K | 13 TB | 12.3B | 0.7B |
| 10–15min caption | 350K | 65 TB | 26.3B | 4.0B |
| Total | ~8M | ~139 TB | 95.1B | 9.9B |
Image tokens are computed at 392×392 input, ViT patch size 14, and vision merge size 2×2 for 196 visual tokens per frame. Caption tokens are measured with the Qwen3 tokenizer over 1,500 sampled clips per bucket, then scaled by row count.
Training Pipeline训练流程
The full LLaVA-OneVision-2 recipe runs in four stages — each stage upgrades a different capability of the model. No instruction data is synthesized; the only synthesized data are video captions.
Stage 1 — Bootstrap from LLaVA-OneVision-1.5 + 30s Video Caption
Lift the image-pretrained LLaVA-OneVision-1.5 8B into a video-aware model by mixing in short 30-second clip captions.
- aLLaVA-OneVision-1.5-Mid-Training-85M — 85M concept-balanced image-text pairs (20M ZH + 65M EN).
- b30s-Video-Caption-4.2M — 4.2M clips, 30 frames @ 392×392.NEW
Stage 2 — Instruction Tuning + 30–60s Video Caption
Scale up to large-scale multimodal instruction data and extend video understanding to medium-length 30–60s clips.
- aLLaVA-OneVision-1.5-Instruct-Data — 22M multimodal instruction samples.
- bHuggingFaceM4/FineVision — 24M instruction samples.
- c30s-60s-Video-Caption-2.7M — medium-length clips, 60 frames @ 392×392.NEW
- d60s-180s-Video-Caption-700K — minute-scale clips, 90 frames @ 392×392.NEW
Stage 3 — Long Video Understanding
Push the model to long-form video reasoning by combining 10–15 minute captions with established video instruction corpora.
- aLLaVA-OneVision-1.5-Instruct-Data — 22M multimodal instruction samples.
- bHuggingFaceM4/FineVision — 24M instruction samples.
- clmms-lab/LLaVA-Video-178K — 1.6M video instruction samples (captions, open-ended and MC QA).
- dOpenGVLab/VideoChat-Flash-Training-Data — long-context video instruction data.
- e10min-15min-Video-Caption-350K — long videos, 384 frames @ 392×392.NEW
Stage 4 — Longer Video + Improved Codec + Spatial & Tracking
Extend to longer videos with an improved codec and denser frame sampling up to 768f, then inject spatial reasoning and video tracking supervision.
- aLLaVA-OneVision-1.5-Instruct-Data — 22M multimodal instruction samples.
- bHuggingFaceM4/FineVision — 24M instruction samples.
- callenai/Molmo2-VideoTrack + allenai/Molmo2-VideoPoint — point-based video tracking and spatio-temporal pointing.
- d10min-15min-Video-Caption-350K (re-encoded) — long videos with the new codec, 384 frames @ 392×392.NEW
- e10min-15min-Video-Caption-350K @ 768f — the same corpus densified to 768 frames @ 392×392.NEW
- fLLaVA-OneVision-2-Spatial-4M — 4M in-house spatial understanding samples.NEW
Visual Encoder Pretraining (OneVision-Encoder)视觉编码器预训练(OneVision-Encoder)
OneVision-Encoder extends native-resolution training to longer aspect ratios and pushes context capacity for high-density documents and frame-rich video.
Open-Source Resources开源资源
The OV2 site ships a small but complete release stack: training code, a public demo surface, the 8B instruct checkpoint, and the full training dataset collection.
Code Demos代码示例
Run LLaVA-OneVision-2-8B-Instruct from a HuggingFace transformers checkpoint (trust_remote_code=True). Two video backends are available: uniform frame sampling, and a codec-aware canvas-packing backend recommended for long videos.以 HuggingFace transformers 权重运行 LLaVA-OneVision-2-8B-Instruct(需 trust_remote_code=True)。提供两种视频后端:均匀抽帧,以及面向长视频推荐的 codec 画布打包后端。
import torch
from transformers import AutoProcessor, AutoModelForImageTextToText
from PIL import Image

MODEL_ID = "lmms-lab-encoder/LLaVA-OneVision-2-8B-Instruct"

processor = AutoProcessor.from_pretrained(MODEL_ID, trust_remote_code=True)
model = AutoModelForImageTextToText.from_pretrained(
    MODEL_ID, trust_remote_code=True, dtype=torch.bfloat16, device_map="cuda",
).eval()

# ----- Image -----
image = Image.open("cat.jpg").convert("RGB")
messages = [{"role": "user", "content": [
    {"type": "image"},
    {"type": "text", "text": "Describe this image in detail."},
]}]
text = processor.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
inputs = processor(text=[text], images=[image], return_tensors="pt", padding=True)
inputs = {k: v.to("cuda") if hasattr(v, "to") else v for k, v in inputs.items()}

out = model.generate(**inputs, max_new_tokens=256, do_sample=False)
print(processor.tokenizer.decode(out[0, inputs["input_ids"].shape[-1]:], skip_special_tokens=True))

# ----- Video -----
# Lower max_pixels if you hit OOM on long videos.
processor.video_processor.max_pixels = 200704

messages = [{"role": "user", "content": [
    {"type": "video"},
    {"type": "text", "text": "Describe what happens in this video."},
]}]
text = processor.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
inputs = processor(
    text=[text], videos=["clip.mp4"], return_tensors="pt", padding=True,
    num_frames=16,  # exact frame count; or use target_fps / max_frames
)
inputs = {k: v.to("cuda") if hasattr(v, "to") else v for k, v in inputs.items()}
out = model.generate(**inputs, max_new_tokens=256, do_sample=False)
print(processor.tokenizer.decode(out[0, inputs["input_ids"].shape[-1]:], skip_special_tokens=True))# Make sure: `pip install codec-video-prep opencv-python` and ffmpeg on PATH.
messages = [{"role": "user", "content": [
{"type": "video"},
{"type": "text", "text": "Describe what happens in this long video."},
]}]
text = processor.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
inputs = processor(
text=[text],
videos=["long_clip.mp4"],
video_backend="codec",
max_pixels=150000, # per-canvas pixel budget; lower if OOM
return_tensors="pt",
padding=True,
# Optional: override codec defaults from preprocessor_config.json
# codec_config={"target_canvas": 32, "group_size": 32, "images_per_group": 4},
)
inputs = {k: v.to("cuda") if hasattr(v, "to") else v for k, v in inputs.items()}
out = model.generate(**inputs, max_new_tokens=256, do_sample=False)
print(processor.tokenizer.decode(out[0, inputs["input_ids"].shape[-1]:], skip_special_tokens=True))Task Demos任务演示
Qualitative results across four downstream capabilities: temporal grounding, referring video segmentation and tracking, spatial grounding, and real-world video manipulation.
Put the apple on the green plate placed on the table.
Robot rollout

9 predicted (x, y, z) waypoints at t = 0 s
Put the bread into the oven.
Robot rollout

5 predicted (x, y, z) waypoints at t = 0 s
Please point to the top piece of paper on the white table.

2D pixel-coordinate point
Pick up the brown small bottle on the table, and move it to the left of the white mouse.

3D pick-and-place trajectory
Please point out the white object that is the second closest to the wooden shelf.

2D pixel-coordinate point
Pick up the gray toy on the left, and move it so spacing matches the other toys.

3D pick-and-place trajectory
Please point to the left pillow on the sofa.

2D pixel-coordinate point
Pick up the red object on the rightmost table, and move it onto the center cabinet.

3D pick-and-place trajectory
Please point out the free space between the cat tree and litter box.

2D pixel-coordinate point
Pick up the calculator on the right table, and move it to the left of the phone on the left table.

3D pick-and-place trajectory
Please point out the free space on the table between the speaker to the right of the monitor and the mouse.

2D pixel-coordinate point
Please point out the object on the windowsill farthest from the viewer.

2D pixel-coordinate point
Please point out the free space between the black water bottle, the pot lid, and the scissors.

2D pixel-coordinate point
Please point out the free space between the black water bottle and the pot lid.

2D pixel-coordinate point
Citation引用
@article{llava_onevision_2_2026,
  title   = {LLaVA-OneVision-2: Open Multimodal Training at Scale},
  author  = {Xiang An and Yin Xie and Kaicheng Yang and Wenkang Zhang and Xiuwei Zhao and Zheng Cheng and Yirui Wang and Songcen Xu and Changrui Chen and Didi Zhu and Chunsheng Wu and Huajie Tan and Chunyuan Li and Jing Yang and Jie Yu and Xiyao Wang and Bin Qin and Yumeng Wang and Zizhen Yan and Ziyong Feng and Ziwei Liu and Bo Li and Jiankang Deng},
  journal = {arXiv preprint arXiv:TBD},
  year    = {2026}
}References参考文献
- LLaVA-OneVision: Easy Visual Task TransferTMLR · 2024arXiv:2408.03326
- LLaVA-OneVision-1.5: Fully Open Framework for Democratized Multimodal TrainingarXiv · 2025arXiv:2509.23661
- OneVision-Encoder: Codec-Aligned Sparsity as a Foundational Principle for Multimodal IntelligencearXiv · 2026arXiv:2602.08683
- Visual Instruction TuningNeurIPS · 2023arXiv:2304.08485
- Qwen3-VL Technical ReportTech Report · 2025github.com/QwenLM/Qwen3-VL
- InternVL3.5: Advancing Open-Source Multimodal Models in Versatility, Reasoning, and EfficiencyTech Report · 2025arXiv:2508.18265
- PerceptionLM: Open-Access Data and Models for Detailed Visual UnderstandingarXiv · 2025arXiv:2504.13180
- Kwai Keye-VL 1.5 Technical ReportarXiv · 2025arXiv:2509.01563